
57 posts
 Climate7 min
What Is COP31 in Antalya? Dates, Hosting Deal and Key Issues
COP31 runs 9–20 November 2026 in Antalya. What a COP is, how the Türkiye–Australia presidency split works, what is on the table and why it matters.
 Cost7 min
Prefix Caching Economics: When Does the Cache Actually Pay?
Cache reads cost 0.1x, writes 1.25x. Break-even is two requests. So why is your cache silently doing nothing? Minimum prefixes, the 20-block rule and the parallel trap.
 Infrastructure7 min
Speculative Decoding: Getting Faster Tokens From the Same Model
Draft models, EAGLE, MTP, n-gram and suffix decoding. Why acceptance rate is the only metric that matters, how to configure vLLM, and when speculation does not help.
 Efficiency7 min
Quantization in Production: FP8, NVFP4, and Where Quality Actually Drops
How to choose between FP8, NVFP4, AWQ and GPTQ: the hardware support matrix, serving with vLLM, and why low-bit quantization degrades non-English output first.
 Architecture8 min
Compaction or Reset? Managing Context in Long Agent Sessions
What to do when the context window fills up: context editing, the clear_tool_uses strategy, server-side compaction and full context resets — with a decision rule.
 Security9 min
Defeating Prompt Injection by Design: CaMeL and Capability-Based Defence
Better prompts do not solve prompt injection. CaMeL, the dual-LLM pattern, capability-based policy and the lethal trifecta — defences enforced outside the model.
 Product8 min
MCP Apps: Interactive UI Inside the Conversation
The MCP Apps extension turns tool results into interactive UI. ui:// resources, the _meta.ui field, sandboxed iframes and the postMessage protocol, with real code.
 Tools7 min
A2A: How Agents Talk to Each Other — and Why It Isn't MCP's Rival
A2A v1.0 standardises agent discovery and task delegation. Agent Cards, the task lifecycle, how it differs from MCP, and the agentic commerce layer above it.
 Agents6 min
Multi-Agent Systems: 15× the Tokens, 90% Better — Which One Is You?
When multi-agent architectures win and when they burn money: reconciling two primary sources, the token multiplier, failure modes and a concrete decision table.
- Applications6 min
Erasing Personal Data From a RAG Index — and From Fine-Tuned Weights
A deletion request touches six places: source, chunks, vectors, caches, logs and fine-tuned weights. A practical erasure strategy and schema for each of them.
 Product6 min
Does llms.txt Actually Work? What the Data Says, and What v2 Changed
A 137,210-domain server-log study says llms.txt is barely fetched and Google says it does not use it. So what did v2 change, and what actually moves AI citations?
- Observability5 min
OpenTelemetry GenAI: Tracing Agents on a Standard Schema
The gen_ai.* conventions are still unstable, and they are still the only standard for agent tracing. The span tree, operation names, MCP propagation, and version pinning.
 Evaluation6 min
Prompt Regression Testing: Putting Evals in CI
Build a golden set from production logs, wire a promptfoo CI gate, calibrate an LLM judge, and avoid the string-matching traps that break non-English evals.
 Cost5 min
From Thinking Budgets to Effort Levels: What Reasoning Actually Costs
You pay for hidden thinking tokens. Effort levels replaced thinking budgets, task budgets arrived, caching breaks when you change them, and more thinking can hurt.
 Security6 min
Agent Sandboxing and Permissions: Avoiding the Lethal Trifecta
The lethal trifecta, the rule of two, a tool permission matrix, container isolation, egress filtering and an audit-log schema that doubles as a compliance trail.
 Agents6 min
Agent Memory Systems: What Lives Outside the Context Window
How agent memory actually works: episodic, semantic and procedural stores, a real pgvector schema, the tool landscape, and controls against memory poisoning.
 Architecture6 min
Agent Harness Design: Generator–Evaluator and Context Anxiety
Why long-running agents wrap up early: context anxiety, why resets beat compaction, the generator-evaluator split and file-based handoff between agents.
 Agents7 min
Taking AI Agents to Production: The Demo Works — Does the System?
What it takes to run an AI agent in production: timeouts, idempotency, circuit breakers, prompt versioning, canary rollout and cost per successful task — with code.
 Cost4 min
Enterprise LLM Budgeting: Token Overhead, FX Risk and the Real Unit Cost
A measured token-overhead figure, cache economics and FX exposure combined into a working unit-cost model — and an honest API-versus-self-host break-even.
- Security6 min
MCP Server Security: When the Tool Description Is the Attack
Tool poisoning, rug-pull redefinition, confused deputy and cross-server shadowing: the MCP-specific attack surface, plus a working tool-definition pinning check.
 Security6 min
OWASP Agentic Top 10: What ASI01–ASI10 Mean in Code
Turning each item of the OWASP Agentic Top 10 (2026) into an implementable control — a config, a policy and a test — instead of restating the risk.
- Models7 min
Turkish Language Models in 2026: A Verified Landscape
The Turkish open-weight LLM landscape with a Hugging Face link behind every claim: Cosmos, Kumru, Trendyol, Kanarya, BILGE — and how to spot models that do not exist.
 Architecture6 min
With a 1M-Token Window, Do You Still Need RAG?
Does a 1M-token window make RAG obsolete? Context rot, the measured token cost of non-English text, and a third option: pushing long context into filesystem tool calls.
 Agents7 min
Computer-Use Agents: The 60-Point Gap Between Demo and Production
How computer-use agents actually work: the 83.5% vs 20.6% benchmark gap OSWorld 2.0 exposed, the perceive-ground-act loop, grounding traps and the security model.
 Tools8 min
MCP 2026: Why the Protocol Went Stateless, and What Your Server Must Change
The 2026-07-28 MCP revision removed sessions, the Mcp-Session-Id header and the initialize handshake. MRTR, server/discover and a concrete migration plan.
- Architecture3 min
Context Engineering: The Discipline That Replaced Prompt Engineering
Context engineering is the discipline of deciding which tokens earn a place in a limited context window at each step. Context rot, lost-in-the-middle, pruning and summarisation strategies.
- Agents2 min
Autonomous Agent Architectures: Plan-and-Execute, Agent Fleets and the Cost Reality
Agents are more than a single loop. ReAct, plan-and-execute, supervisor-worker patterns, heterogeneous model use, and how to keep cost under control across agent fleets.
- Models2 min
Small Language Models: When Smaller Beats Bigger
Small language models can beat large ones on high-frequency, narrow tasks. Latency, cost, on-device execution, fine-tuning and the realistic limits.
- Architecture2 min
Model Routing and Cascades: Stop Sending Every Task to the Same Model
Routing sends each request to the model whose cost and capability fit it. Cascade architectures, confidence thresholds, escalation paths and measuring the real cost-quality curve.
- Models2 min
Reasoning Models and Test-Time Compute: Buying Time to Think
Reasoning models generate thinking steps before answering. What test-time compute buys you, when it is wasted, and how it changes latency and cost.
- Tooling3 min
MCP (Model Context Protocol): A Common Language for AI Tooling
MCP gives models a standard interface to tools and data sources. The client-server model, the N-times-M problem, security boundaries and practical use.
- Agents3 min
Agent Evaluation: How Do You Measure a Multi-Step System?
Evaluating an agent is not the same as scoring one answer. Task success, step quality, tool choice, cost and robustness testing in a practical agent evaluation framework.
- Safety2 min
Guardrails: Constraining AI Output in Production
Guardrails are the layer that constrains a model input and output with rules. Input filters, schema validation, output checks, grounding verification and the false-positive trade-off.
- Product3 min
GEO: Getting Cited by Generative Search Engines
Generative search engines answer directly, so citations matter more than clicks. Practical ways to structure content so ChatGPT, Perplexity and AI Overviews quote it.
- Applications3 min
AI in Legal Practice: Why a System Without Citations Is Useless
AI in law demands verifiable accuracy. Case-law search, grounding, mandatory citation, confidentiality, and why final responsibility stays with the lawyer.
- Multimodal7 min
Multimodal Models: How Does AI That Processes Image, Text, and Audio Together Actually Work?
How do multimodal models combine image, text, and audio in a single system? We explain vision-language models, the shared embedding space, and real use cases with intuitive analogies and short code.
- Generative6 min
Diffusion Models and Image Generation: From Noise to Image
How do diffusion models generate images? The forward and reverse processes, the path from noise to image, and Stable Diffusion's latent space — explained intuitively and accurately with everyday analogies.
- Efficiency7 min
Knowledge Distillation and Small Models: Transferring Knowledge from a Large Teacher to a Small Student
Knowledge distillation transfers a large teacher model’s knowledge into a small, fast student model. We explain soft labels, temperature, and the distillation loss, and why, how, and when it works, with intuitive examples.
- Fine-tuning7 min
LoRA and Efficient Fine-Tuning (PEFT): Adapting a Model Without Training the Whole Thing
An intuitive guide to LoRA and PEFT: adapting a model without training all of it, using small low-rank adapters, the memory/cost advantage, and practical usage tips.
- Security8 min
Prompt Injection and Jailbreaks: The Foundations of AI Security
What are prompt injection and jailbreaks, and how do they work? We explain the risks in RAG and agent systems, plus layered defenses, with plain everyday analogies.
- Integration6 min
Function Calling and Structured Output: Turning the Model into a Reliable Component
Function calling and structured output turn a language model from a free-text chatter into a component you can wire into your systems with confidence. We explain JSON generation, schema enforcement, and robust integration practices with intuitive examples.
- Cost9 min
LLM Cost Optimization: Cutting the Bill with Tokens, Caching, Model Choice, and RAG
Practical levers for lowering your LLM bill: reducing token consumption, prompt caching, matching the task to the model, batch processing, and the small model + RAG balance. Cost optimization in the right order, with intuitive analogies and example code.
- Alignment8 min
RLHF and Model Alignment: Helpful and Safe Models, the Reward Model, and DPO
Why and how do we make a model "helpful and safe"? We explain the three steps of RLHF, the reward model, and the simpler alternative DPO using everyday analogies.
- Observability7 min
LLM Observability: A Practical Look at Tracing, Logging, and Evaluation Loops
A plain-language guide to LLM observability: tracing, logging, evaluation loops, and how to protect quality and catch regressions early in production.
- Product7 min
User Experience in AI Products (AI UX): From Uncertainty to Trust
How do you design user experience for AI products? A practical guide to managing uncertainty, citing sources, feedback, graceful failure, and building trust.
- LLM7 min
How Do Large Language Models (LLMs) Work? An Intuitive Guide to the Transformer Architecture
How do LLMs work? An intuitive yet technical guide to the Transformer architecture: next-word prediction, the attention mechanism, and layers explained simply.
- Fundamentals6 min
Tokens and Embeddings: How Does a Language Model "See" Text?
An intuitive guide to tokenization, word pieces, and embedding vectors: how the meaning of text turns into numbers and coordinates inside a language model.
- RAG6 min
What Is RAG and How to Build It End to End: A Practical Architecture Guide
What is RAG and how does it work? A practical, end-to-end architecture guide to document, chunk, embedding, vector search and context-grounded generation, with small code examples.
- Infrastructure5 min
Vector Databases Guide: Similarity Search, HNSW, and FAISS / pgvector / Qdrant Compared
An intuitive guide to vector databases: similarity search, ANN and the HNSW algorithm, a FAISS vs pgvector vs Qdrant comparison, and when to choose each one.
- Practice6 min
Prompt Engineering: Practical Techniques with Real Examples
Clear instructions, few-shot, step-by-step reasoning, role assignment and output formatting: practical techniques to get better results from language models, with examples.
- Decision5 min
Fine-tuning, RAG, or Prompt? When to Use Each Approach
We compare fine-tuning, RAG, and prompting on cost, freshness, and accuracy. Which one should you pick and when? Includes a practical decision table.
- Reliability7 min
LLM Hallucinations: Why They Happen and How to Reduce Them
Why do LLMs hallucinate and how can you reduce it? Practical measures with grounding, RAG, verification, self-checking, and temperature tuning.
- Ecosystem7 min
Open-Source LLMs: A Practical Look at Llama, Mistral, Qwen and Gemma
We compare open-source LLMs like Llama, Mistral, Qwen and Gemma against closed models: privacy, cost, fine-tuning freedom, and when each one wins.
- Evaluation6 min
How Do We Evaluate LLMs? Automatic Metrics, LLM-as-Judge and RAG Faithfulness
A guide to LLM evaluation: automatic metrics, LLM-as-judge, human evaluation, domain-specific test sets, and measuring faithfulness for RAG systems.
- MLOps7 min
Taking an AI Model to Production (MLOps): From Demo to Real Product
What is MLOps? How to take an AI model to production: versioning, monitoring, latency/cost, the feedback loop, and safe deployment, explained in plain language.
 Profile3 min
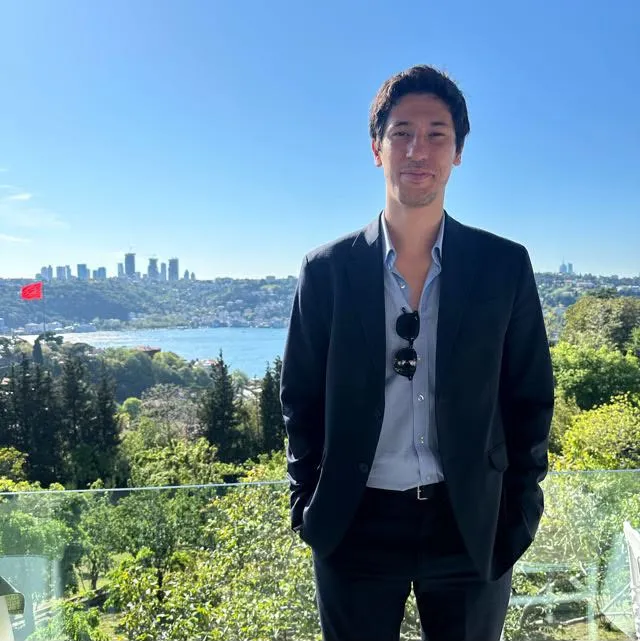
Who is İsmail Tarık Şenkal?
Who is İsmail Tarık Şenkal? The story of the co-founder of Hatson Teknoloji A.Ş. — a developer and entrepreneur working on Turkish artificial intelligence, large language models, and legal technologies.
 Company2 min
How did HatsonTech come about?
How did HatsonTech come about? The origin story of a Turkish AI startup founded in 2024 at ODTÜ Teknokent in Ankara: what problem it set out to solve, and why it builds its own products.